Compare Agents on the Discrete Pendulum Swing-Up
R2026bThis example shows how to create and train frequently used default agents on a discrete action space pendulum swing-up environment. This environment represents a simple frictionless pendulum that initially hangs in a downward position. The agent can apply a control torque on the pendulum, and its goal is to make the pendulum stand upright using minimal control effort. The example plots performance metrics such as the total training time and the total reward for each trained agent.
The results that the agents obtain in this environment, with the selected initial conditions and random number generator seed, do not necessarily imply that specific agents are in general better than others. Also, note that the training times depend on the computer and operating system you use to run the example, and on other processes running in the background. Your training times might differ substantially from the training times shown in the example.
Discrete Action Space Pendulum Swing-Up Model
The reinforcement learning environment for this example is a simple frictionless pendulum that initially hangs in a downward position. The agent can apply a control torque on the pendulum, and its goal is to make the pendulum stand upright using minimal control effort.
Open the model.
mdl = "rlSimplePendulumModel";
open_system(mdl)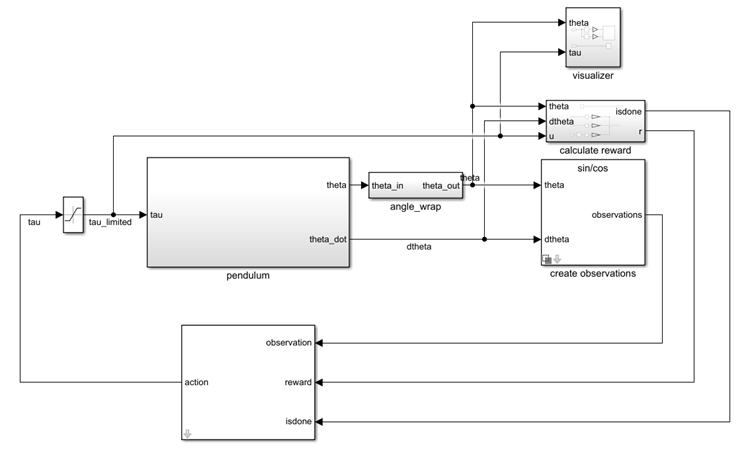
In this model:
The balanced, upright pendulum position is zero radians, and the downward hanging pendulum position is
piradians (the pendulum angle is counterclockwise-positive).The torque (counterclockwise-positive) action can be one of three possible values: –2, 0, or 2 Newtons per meter.
The observations from the environment are the sine, cosine, and derivative of the pendulum angle.
The reward , provided at every timestep, is
Here:
is the angle of displacement from the upright position.
is the derivative of the displacement angle.
is the control effort from the previous time step.
For more information on this model, see Use Predefined Control System Environments.
Specify Random Number Stream Seed and Algorithm for Reproducibility
The example code might involve computation of random numbers at several stages. Fixing the random number stream at the beginning of some sections in the example code preserves the random number sequence in the section every time you run it, which is a necessary condition to reproduce the results. For more information, see Results Reproducibility.
Specify the random number stream with seed zero and random number algorithm Mersenne Twister. For more information on controlling the seed used for random number generation, see rng.
previousRngState = rng(0,"twister");The output previousRngState is a structure that contains information about the previous state of the stream. You will restore the state at the end of the example.
Create Environment Object
Create a predefined environment object for the pendulum.
env = rlPredefinedEnv("SimplePendulumModel-Discrete")env =
SimulinkEnvWithAgent with properties:
Model : rlSimplePendulumModel
AgentBlock : rlSimplePendulumModel/RL Agent
ResetFcn : []
UseFastRestart : on
To define the initial condition of the pendulum as hanging downward, specify an environment reset function using an anonymous function handle. This reset function sets the model workspace variable theta0 to pi.
env.ResetFcn = @(in)setVariable(in,"theta0",pi,"Workspace",mdl);
Reset the environment.
reset(env);
For more information on Simulink® environments and their reset functions, see SimulinkEnvWithAgent.
Specify the agent sample time Ts and the simulation time Tf in seconds.
Ts = 0.05;
Tf = 20;
Get the observation and action specification information from the environment.
obsInfo = getObservationInfo(env)
obsInfo =
  rlNumericSpec with properties:

     LowerLimit: -Inf
     UpperLimit: Inf
           Name: "observations"
    Description: [0×0 string]
      Dimension: [3 1]
       DataType: "double"
actInfo = getActionInfo(env)
actInfo =
  rlFiniteSetSpec with properties:

       Elements: [3×1 double]
           Name: "torque"
    Description: [0×0 string]
      Dimension: [1 1]
       DataType: "double"
Configure Training and Simulation Options for All Agents
Create an evaluation object to evaluate the agent ten times without exploration every 100 training episodes.
evl = rlEvaluator(NumEpisodes=10,EvaluationFrequency=100);
Create a training options object. For this example, use the following options.
Run the training for a maximum of 1000 episodes, with each episode lasting 500 time steps.
Stop the training when the agent receives an average cumulative reward greater than –1100 over five consecutive evaluation episodes. At this point, the agent can quickly balance the pendulum in the upright position using minimal control effort.
To have a better insight on the agent's behavior during training, plot the training progress (default option). If you want to achieve faster training times, set the
Plotsoption tonone.
trainOpts = rlTrainingOptions( ...
    MaxEpisodes=1000, ...
    MaxStepsPerEpisode=500, ...
    StopTrainingCriteria="EvaluationStatistic", ...
    StopTrainingValue=-1100, ...
    Plots="training-progress");
For more information on training options, see rlTrainingOptions.
To simulate the trained agent, create a simulation options object and configure it to simulate for 500 steps.
simOptions = rlSimulationOptions(MaxSteps=500);
For more information on simulation options, see rlSimulationOptions.
Create, Train, and Simulate a Q-learning Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlQAgentOptions object using the environment specification objects.
qAgent = rlQAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of qAgent.
qAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
qAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
qAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic qTngRes = train(qAgent,env,trainOpts,Evaluator=evl); qTngTime = toc; % Extract number of training episodes and total steps. qTngEps = qTngRes.EpisodeIndex(end); qTngSteps = sum(qTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchQData.mat", ... % "qAgent","qTngEps","qTngSteps","qTngTime") else % Load the pretrained agent and the metrics for the example. load("dpsuBchQData.mat", ... "qAgent","qTngEps","qTngSteps","qTngTime") end
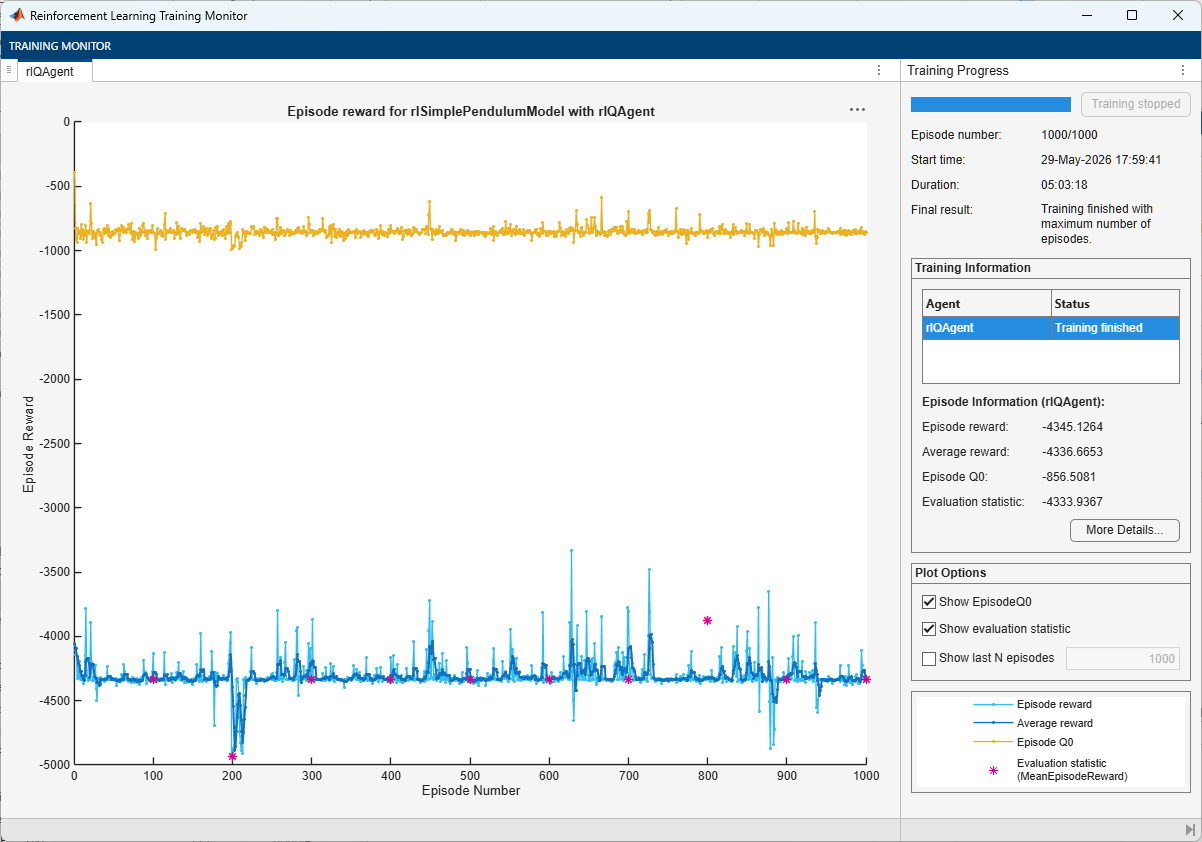
For the Q-learning agent, the training does not converge to a solution. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,qAgent,simOptions);
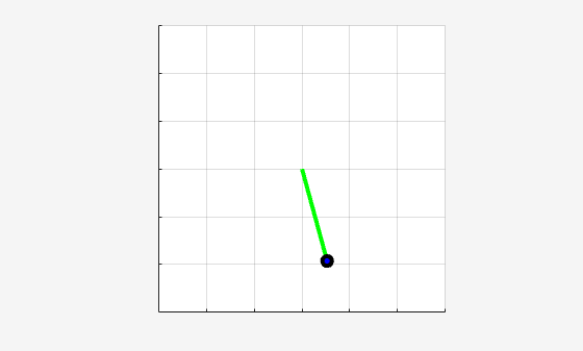
qTotalRwd = sum(experience.Reward)
qTotalRwd =
-4.3339e+03
The trained Q-learning agent is not able to swing up and stabilize the pendulum upright.
Create, Train, and Simulate a SARSA Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlSARSAAgent object using the environment specification objects.
sarsaAgent = rlSARSAAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of sarsaAgent.
sarsaAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
sarsaAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
sarsaAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic sarsaTngRes = train(sarsaAgent,env,trainOpts,Evaluator=evl); sarsaTngTime = toc; % Extract number of training episodes and total steps. sarsaTngEps = sarsaTngRes.EpisodeIndex(end); sarsaTngSteps = sum(sarsaTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchSARSAData.mat", ... % "sarsaAgent","sarsaTngEps","sarsaTngSteps","sarsaTngTime") else % Load the pretrained agent and the metrics for the example. load("dpsuBchSARSAData.mat", ... "sarsaAgent","sarsaTngEps","sarsaTngSteps","sarsaTngTime") end
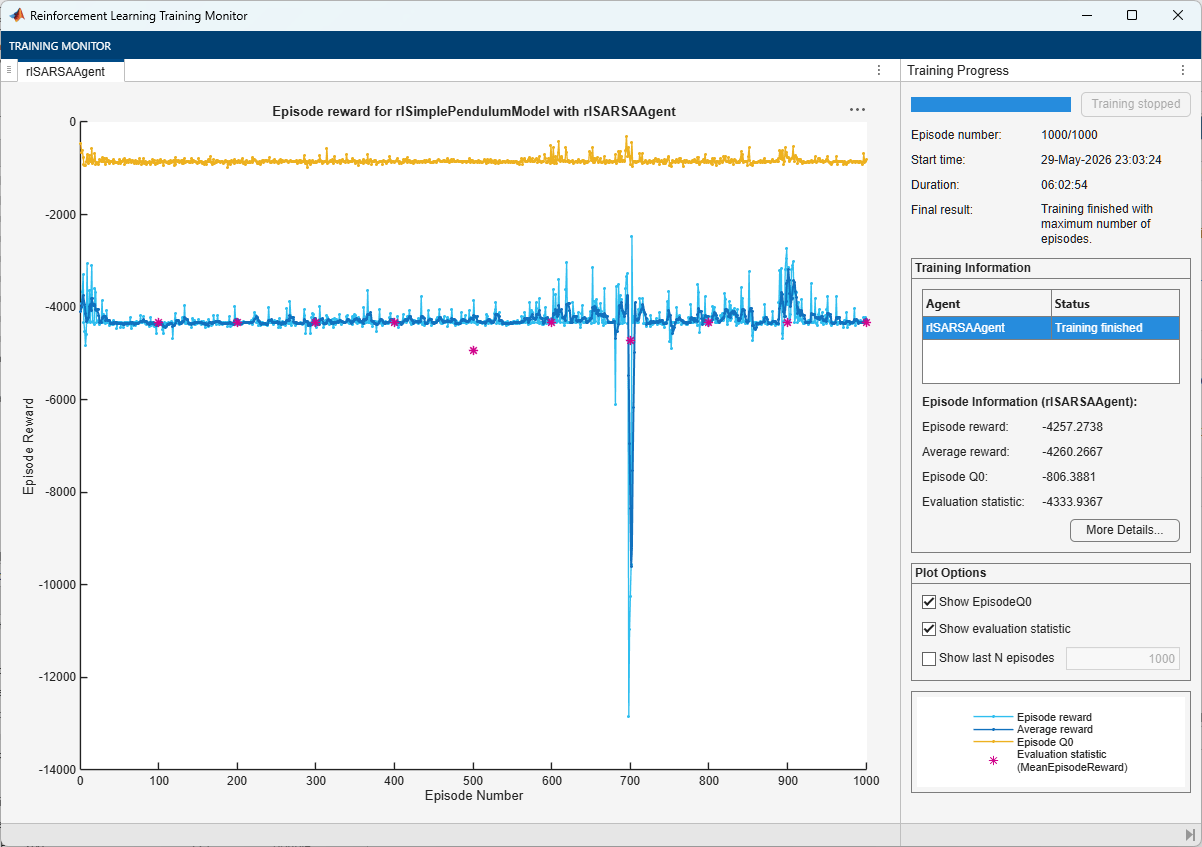
For the SARSA agent, the training does not converge to a solution. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
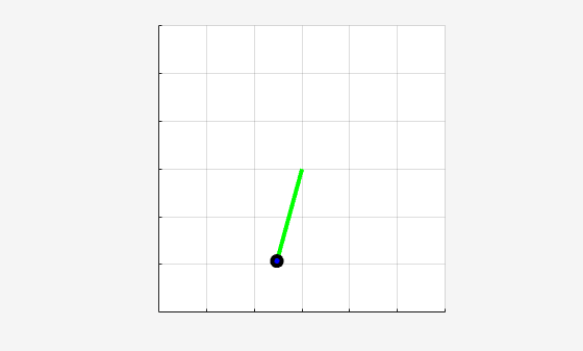
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,sarsaAgent,simOptions);
sarsaTotalRwd = sum(experience.Reward)
sarsaTotalRwd =
-4.3339e+03
The trained SARSA agent is not able to swing up and stabilize the pendulum upright.
Create, Train, and Simulate a DQN Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlDQNAgent object using the environment specification objects.
dqnAgent = rlDQNAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of dqnAgent.
dqnAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
dqnAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
dqnAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
Use a larger experience buffer to store more experiences, therefore decreasing the likelihood of catastrophic forgetting.
dqnAgent.AgentOptions.ExperienceBufferLength = 1e6;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic dqnTngRes = train(dqnAgent,env,trainOpts,Evaluator=evl); dqnTngTime = toc; % Extract number of training episodes and total steps. dqnTngEps = dqnTngRes.EpisodeIndex(end); dqnTngSteps = sum(dqnTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchDQNData.mat", ... % "dqnAgent","dqnTngEps","dqnTngSteps","dqnTngTime") else % Load the pretrained agent and the metrics for the example. load("dpsuBchDQNData.mat", ... "dqnAgent","dqnTngEps","dqnTngSteps","dqnTngTime") end
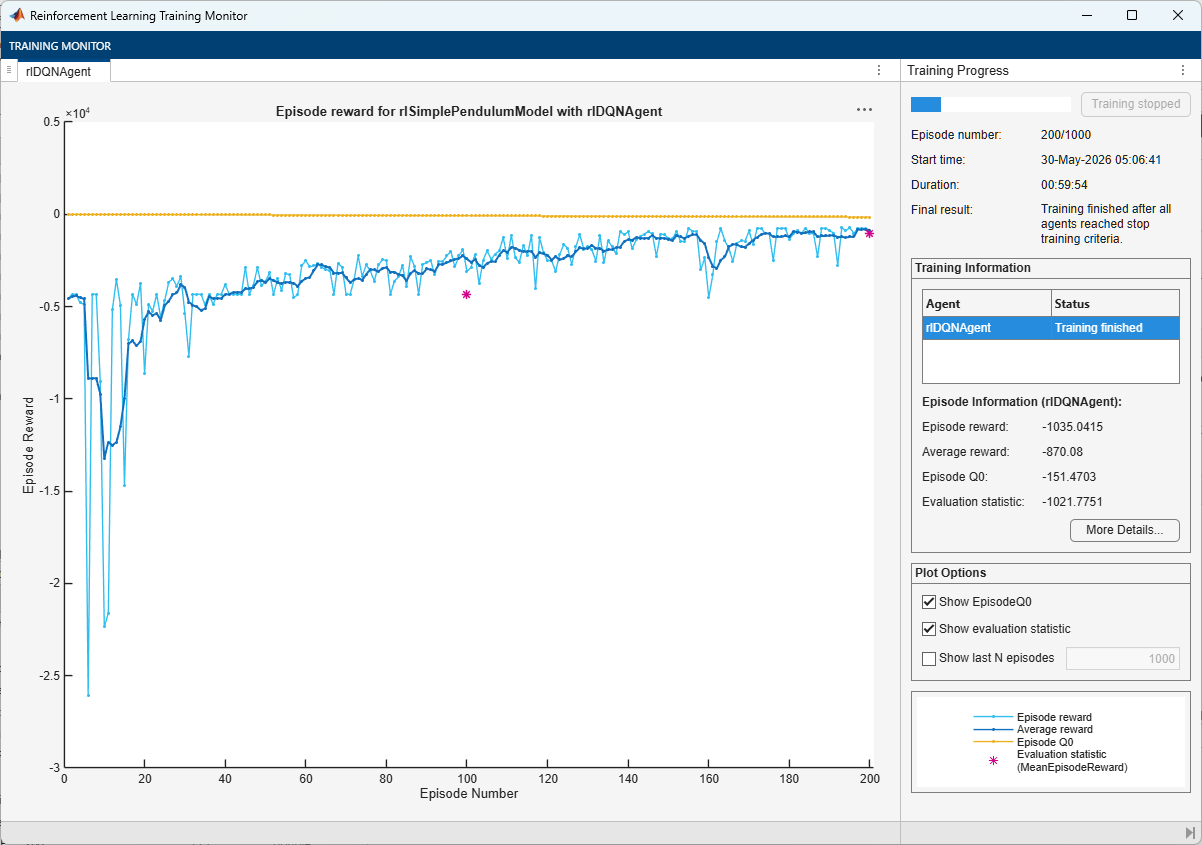
For the DQN agent, the training converges to a solution after 200 episodes. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
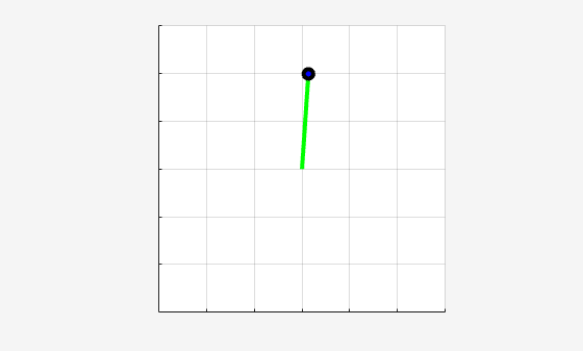
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,dqnAgent,simOptions);
dqnTotalRwd = sum(experience.Reward)
dqnTotalRwd =
-1.0218e+03
The trained DQN agent is able to swing up and stabilize the pendulum upright.
Create, Train, and Simulate a PG Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlPGAgent object using the environment specification objects.
pgAgent = rlPGAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of pgAgent.
pgAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
pgAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
pgAgent.AgentOptions.ActorOptimizerOptions.LearnRate = 1e-3;
pgAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
pgAgent.AgentOptions.ActorOptimizerOptions.GradientThreshold = 1;
Set the entropy loss weight to increase exploration.
acAgent.AgentOptions.EntropyLossWeight = 0.005;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic pgTngRes = train(pgAgent,env,trainOpts,Evaluator=evl); pgTngTime = toc; % Extract number of training episodes and total steps. pgTngEps = pgTngRes.EpisodeIndex(end); pgTngSteps = sum(pgTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchPGData.mat", ... % "pgAgent","pgTngEps","pgTngSteps","pgTngTime") else % Load the pretrained agent and the metrics for the example. load("dpsuBchPGData.mat", ... "pgAgent","pgTngEps","pgTngSteps","pgTngTime") end
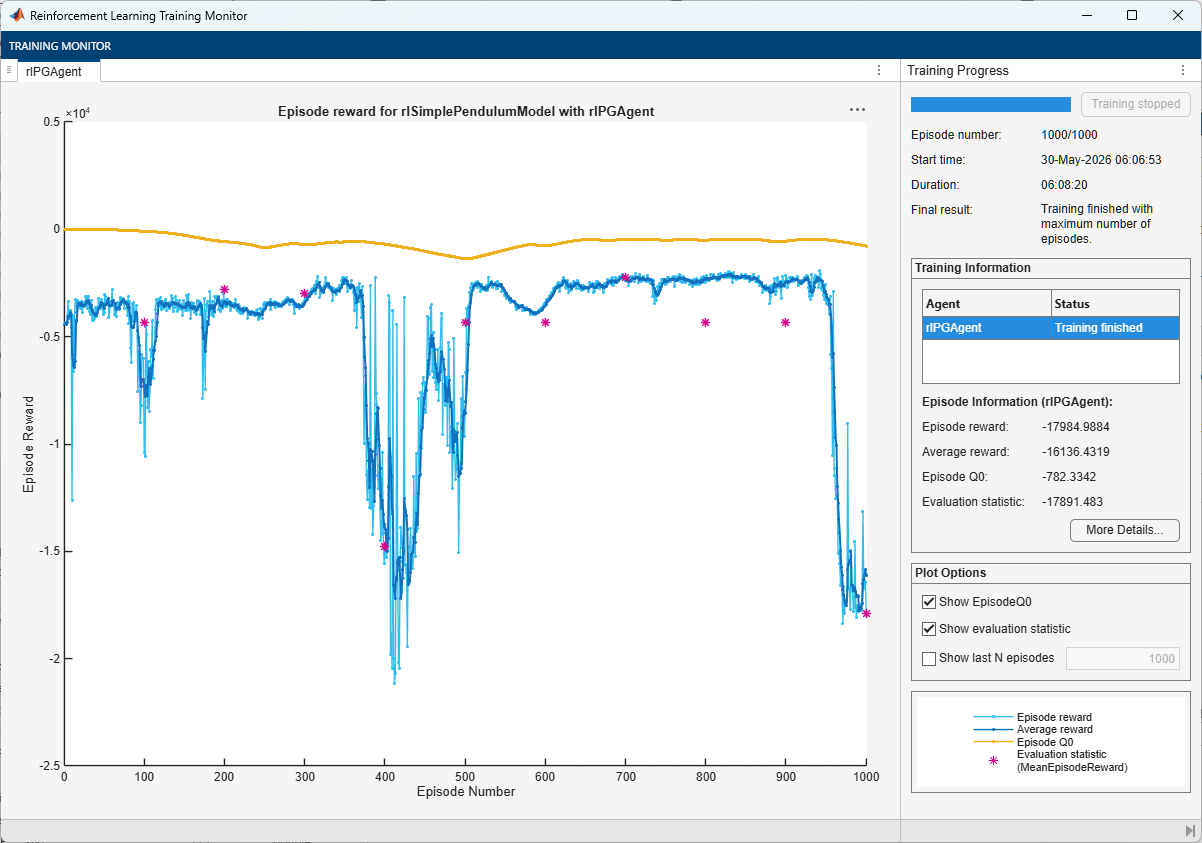
For the PG agent, the training does not converge to any solution after 1000 episodes. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,pgAgent,simOptions);
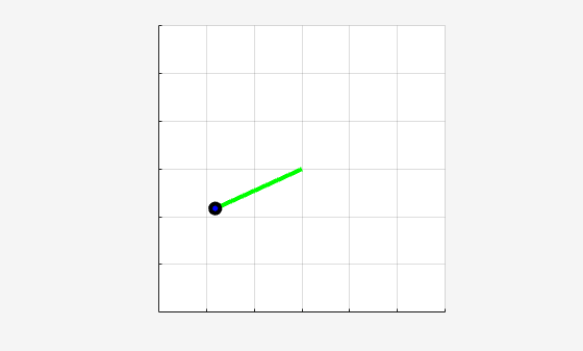
pgTotalRwd = sum(experience.Reward)
pgTotalRwd =
-1.7859e+04
The trained PG agent is not able to swing up the pendulum.
Create, Train, and Simulate an AC Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlACAgent object using the environment specification objects.
acAgent = rlACAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of acAgent.
acAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
acAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
acAgent.AgentOptions.ActorOptimizerOptions.LearnRate = 1e-3;
acAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
acAgent.AgentOptions.ActorOptimizerOptions.GradientThreshold = 1;
Set the entropy loss weight to increase exploration.
acAgent.AgentOptions.EntropyLossWeight = 0.005;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic acTngRes = train(acAgent,env,trainOpts,Evaluator=evl); acTngTime = toc; % Extract number of training episodes and total steps. acTngEps = acTngRes.EpisodeIndex(end); acTngSteps = sum(acTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchACData.mat", ... % "acAgent","acTngEps","acTngSteps","acTngTime") else % Load the pretrained agent and the metrics for the example. load("dpsuBchACData.mat", ... "acAgent","acTngEps","acTngSteps","acTngTime") end
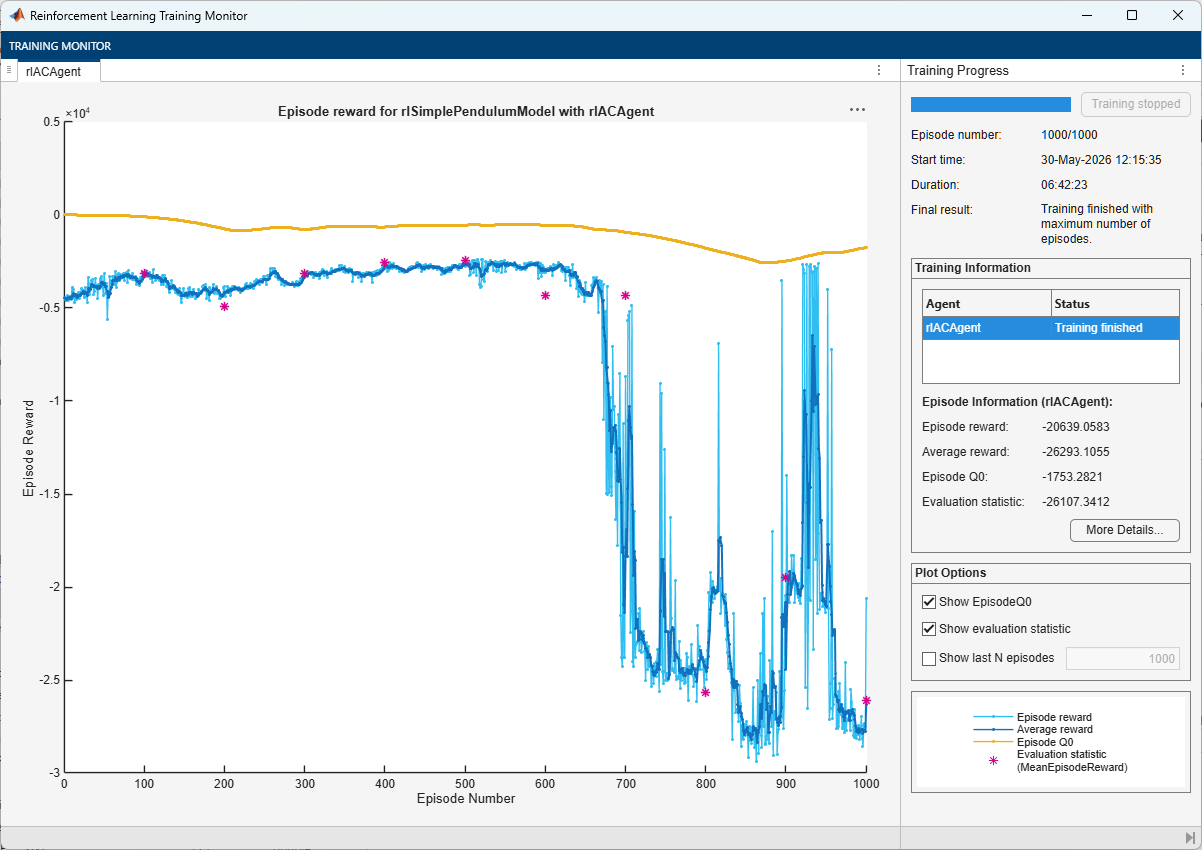
For the AC agent, as for the PG agent, the training does not converge to a solution after 1000 episodes. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,acAgent,simOptions);
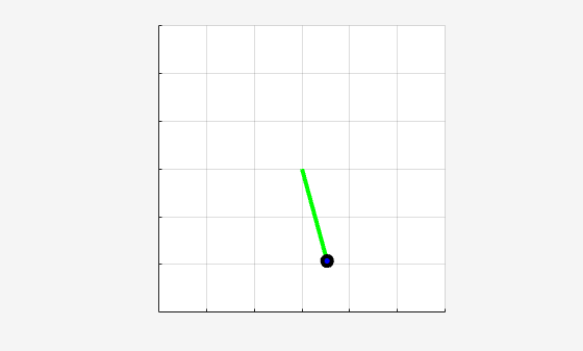
acTotalRwd = sum(experience.Reward)
acTotalRwd =
-4.3339e+03
The trained AC agent is not able to swing up the pendulum.
Create, Train, and Simulate a PPO Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlPPOAgent object using the environment specification objects.
ppoAgent = rlPPOAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of ppoAgent.
ppoAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
ppoAgent.AgentOptions.CriticOptimizerOptions.LearnRate = 1e-3;
ppoAgent.AgentOptions.ActorOptimizerOptions.LearnRate = 1e-3;
ppoAgent.AgentOptions.CriticOptimizerOptions.GradientThreshold = 1;
ppoAgent.AgentOptions.ActorOptimizerOptions.GradientThreshold = 1;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic ppoTngRes = train(ppoAgent,env,trainOpts,Evaluator=evl); ppoTngTime = toc; % Extract number of training episodes and total steps. ppoTngEps = ppoTngRes.EpisodeIndex(end); ppoTngSteps = sum(ppoTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchPPOData.mat", ... % "ppoAgent","ppoTngEps","ppoTngSteps","ppoTngTime") else % Load the pretrained agent and results for the example. load("dpsuBchPPOData.mat", ... "ppoAgent","ppoTngEps","ppoTngSteps","ppoTngTime") end
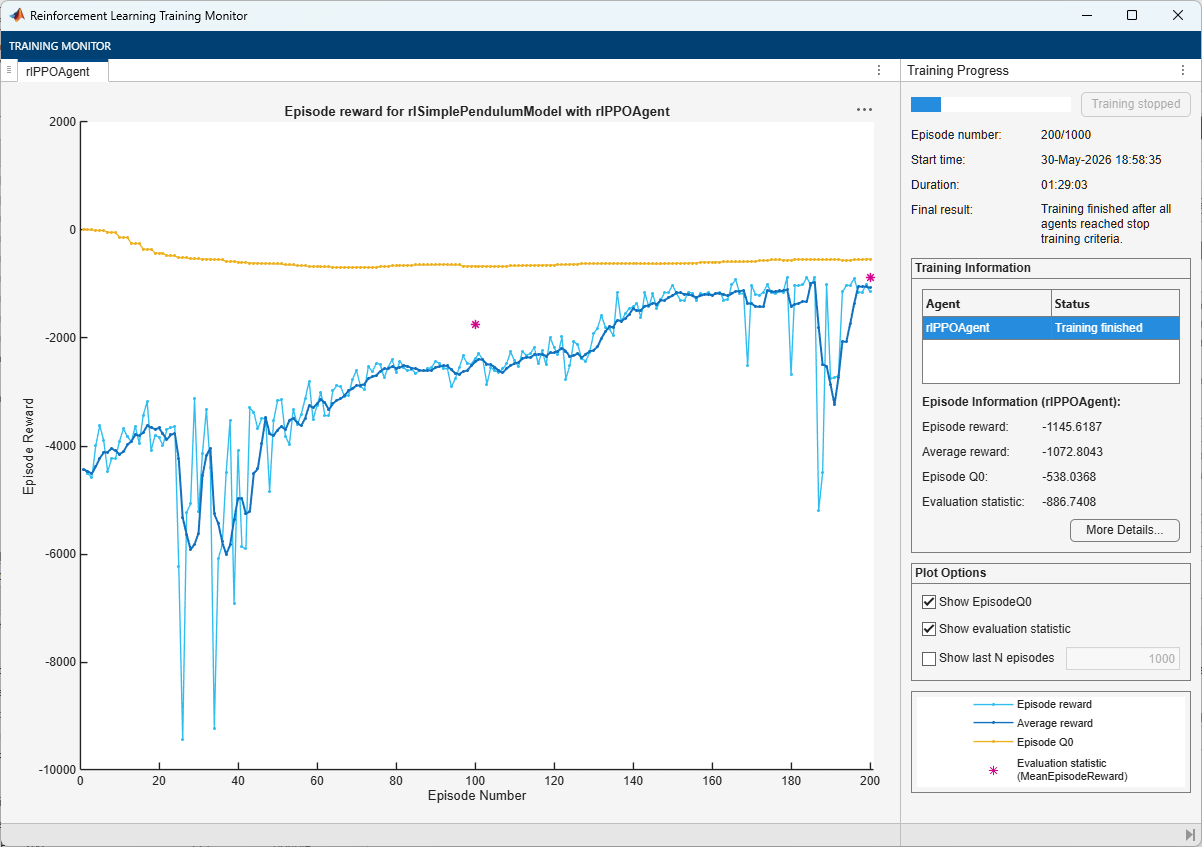
For the PPO agent, the training converges to a solution after 200 episodes. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
Simulate the environment with the trained agent for 500 steps and display the total reward. For more information on agent simulation, see sim.
experience = sim(env,ppoAgent,simOptions);
ppoTotalRwd = sum(experience.Reward)
ppoTotalRwd =
-886.7408
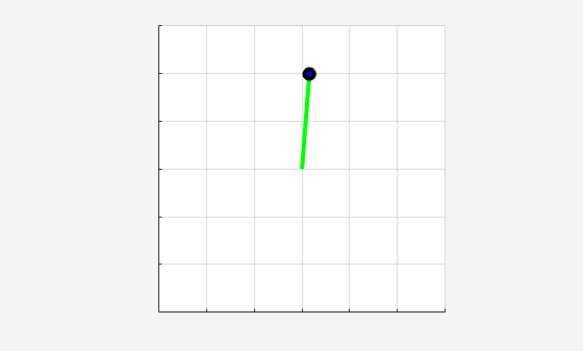
The trained PPO agent swings up and stabilizes the pendulum in the upright position.
Create, Train, and Simulate a SAC Agent
The constructor functions initialize the agent networks randomly. To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")Create a default rlSACAgent object using the environment specification objects.
sacAgent = rlSACAgent(obsInfo,actInfo);
To ensure that the RL Agent block in the environment executes every Ts seconds instead of the default setting of one second, set the SampleTime property of ppoAgent.
sacAgent.AgentOptions.SampleTime = Ts;
Set a lower learning rate and a lower gradient threshold to promote a smoother (though possibly slower) training.
sacAgent.AgentOptions.CriticOptimizerOptions(1).LearnRate = 1e-3;
sacAgent.AgentOptions.CriticOptimizerOptions(2).LearnRate = 1e-3;
sacAgent.AgentOptions.CriticOptimizerOptions(1).GradientThreshold = 1;
sacAgent.AgentOptions.CriticOptimizerOptions(2).GradientThreshold = 1;

sacAgent.AgentOptions.ActorOptimizerOptions.LearnRate = 1e-3;
sacAgent.AgentOptions.ActorOptimizerOptions.GradientThreshold = 1;
Set the initial entropy weight and target entropy to increase exploration.
sacAgent.AgentOptions.EntropyWeightOptions.EntropyWeight = 5e-3;
sacAgent.AgentOptions.EntropyWeightOptions.TargetEntropy = 5e-1;
Use a larger experience buffer to store more experiences, therefore decreasing the likelihood of catastrophic forgetting.
sacAgent.AgentOptions.ExperienceBufferLength = 1e6;
Train the agent, passing the agent, the environment, and the previously defined training options and evaluator objects to train. Training is a computationally intensive process that takes several minutes to complete. To save time, load a pretrained agent by setting doTraining to false. To train the agent yourself, set doTraining to true.
doTraining =false; if doTraining % Train the agent. Record the training time. tic sacTngRes = train(sacAgent,env,trainOpts,Evaluator=evl); sacTngTime = toc; % Extract number of training episodes and total steps. sacTngEps = sacTngRes.EpisodeIndex(end); sacTngSteps = sum(sacTngRes.TotalAgentSteps); % Uncomment to save the trained agent and the training metrics. % save("dpsuBchSACData.mat", ... % "sacAgent","sacTngEps","sacTngSteps","sacTngTime") else % Load the pretrained agent and results for the example. load("dpsuBchSACData.mat", ... "sacAgent","sacTngEps","sacTngSteps","sacTngTime") end
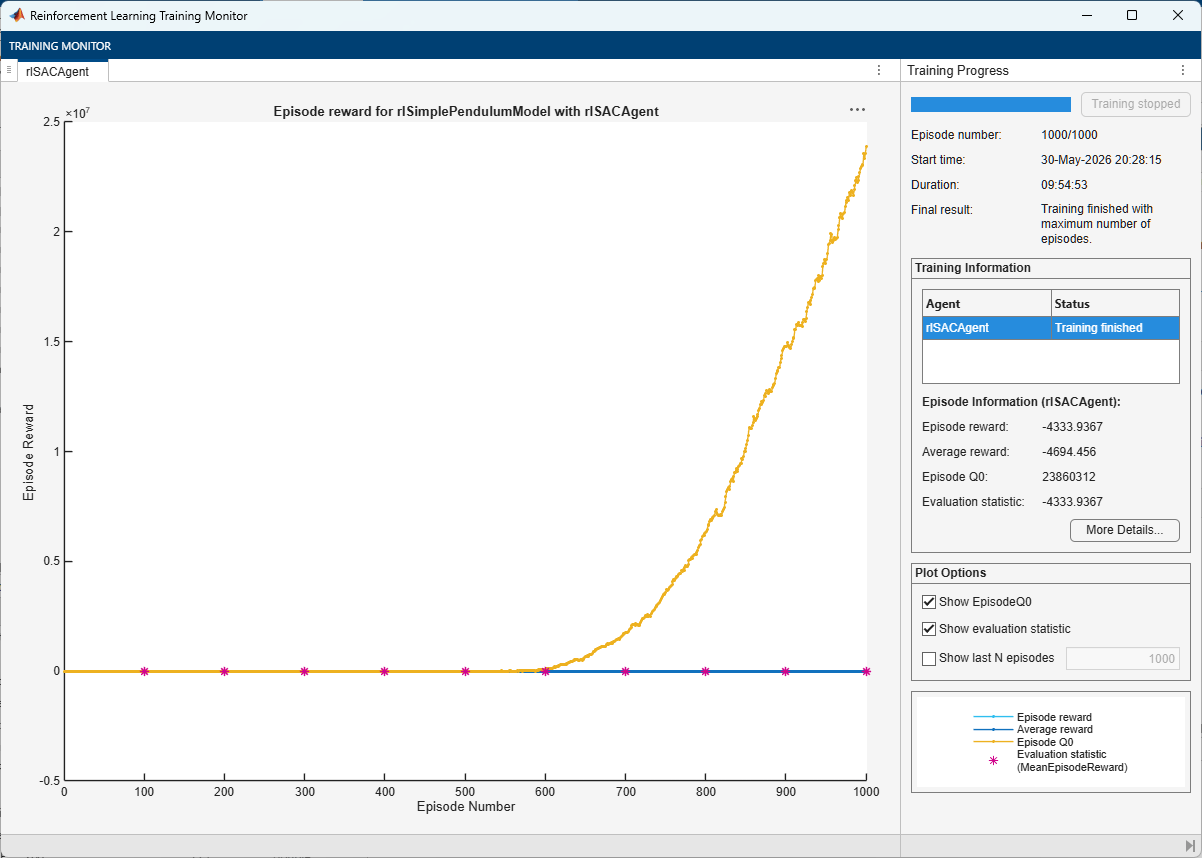
For the SAC agent, the training does not converge to a solution. In the following section, check the trained agent within the pendulum swing-up environment.
To reproduce the results of this section, specify the seed and algorithm used for random number generation.
rng(0,"twister")By default, the agent uses a greedy (hence deterministic) policy in simulation. To use the exploratory policy instead, set the UseExplorationPolicy agent property to true.
Simulate the environment with the trained agent for 500 steps. For more information on agent simulation, see rlSimulationOptions and sim.
experience = sim(env,sacAgent,simOptions);
sacTotalRwd = sum(experience.Reward)
sacTotalRwd =
-4.3339e+03
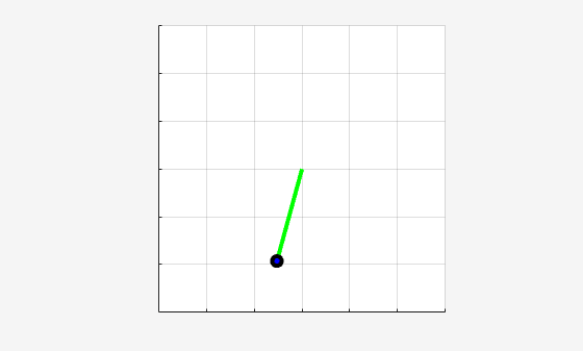
The trained SAC agent is able to swing up and stabilize the pendulum upright.
Plot Training and Simulation Metrics
For each agent, collect the total reward from the final simulation episode, the number of training episodes, the total number of agent steps, and the total training time as shown in the Reinforcement Learning Training Monitor.
simReward = [
    dqnTotalRwd
    ppoTotalRwd
    ];

tngEpisodes = [
    dqnTngEps
    ppoTngEps
    ];

tngSteps = [
    dqnTngSteps
    ppoTngSteps
    ];

tngTime = [
    dqnTngTime
    ppoTngTime
    ];
Plot the simulation reward, number of training episodes, number of training steps (that is, the number of interactions between the agent and the environment) and the training time for the two agents that swing up and stabilize the pendulum. Scale the data by the factor [0.75 0.5 1e4 3] for better visualization.
bar([simReward,tngEpisodes,tngSteps,tngTime]./[0.75 0.5 1e4 3])
xticklabels(["DQN" "PPO"])
legend( ...
        ["Simulation Reward", ...
        "Training Episodes", ...
        "Training Steps", ...
        "Training Time"], ...
    "Location", "northwest")
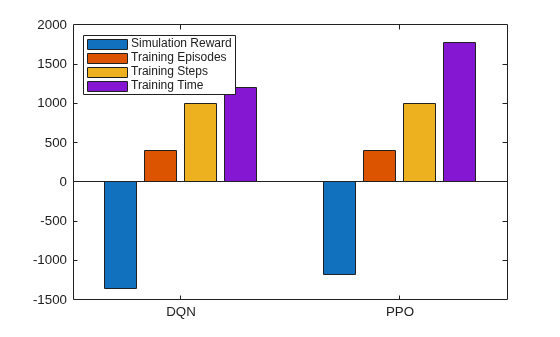
Both agent use the same number of episodes and take the same number of steps. The PPO agent takes slightly longer to train but achieves a slightly better reward in simulation. With a different random seed, the initial agent networks would be different, and therefore, convergence results might be different. For more information on the relative strengths and weaknesses of each agent, see Reinforcement Learning Agents.
Save all the variables created in this example, including the training results, for later use.
% Uncomment to save all the workspace variables
% save dpsuAllVariables.mat
Restore the random number stream using the information stored in previousRngState.
rng(previousRngState);

